 Gangnam Style AI
Input to output
Three portraits. One finished dance.
See the three AI-generated adult portraits used for the public demo and the 15-second output they produced through the same fixed workflow available here.
Before
Input portraits
One clear adult portrait for each position, shown from the viewer’s perspective.
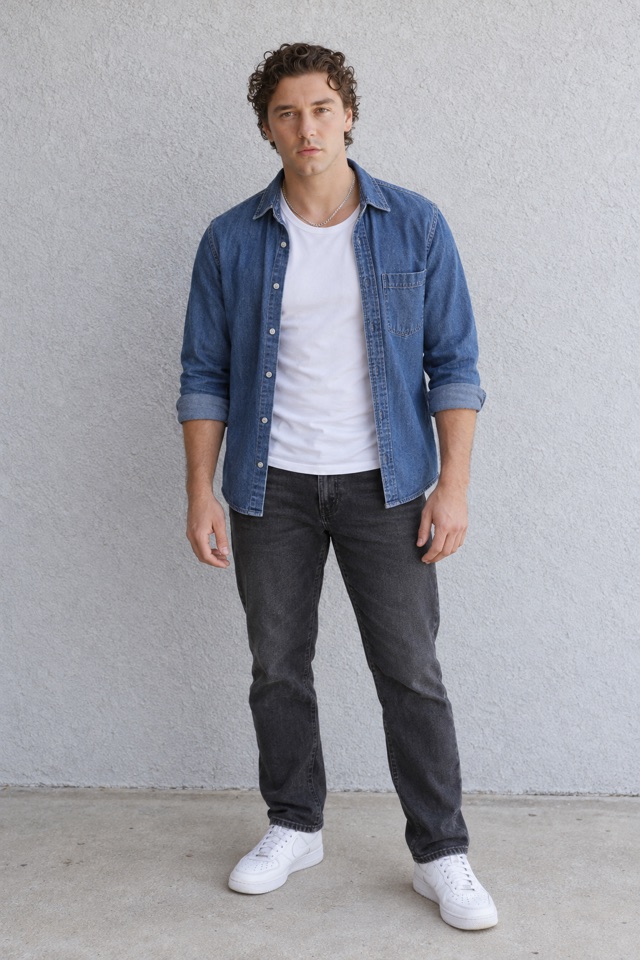
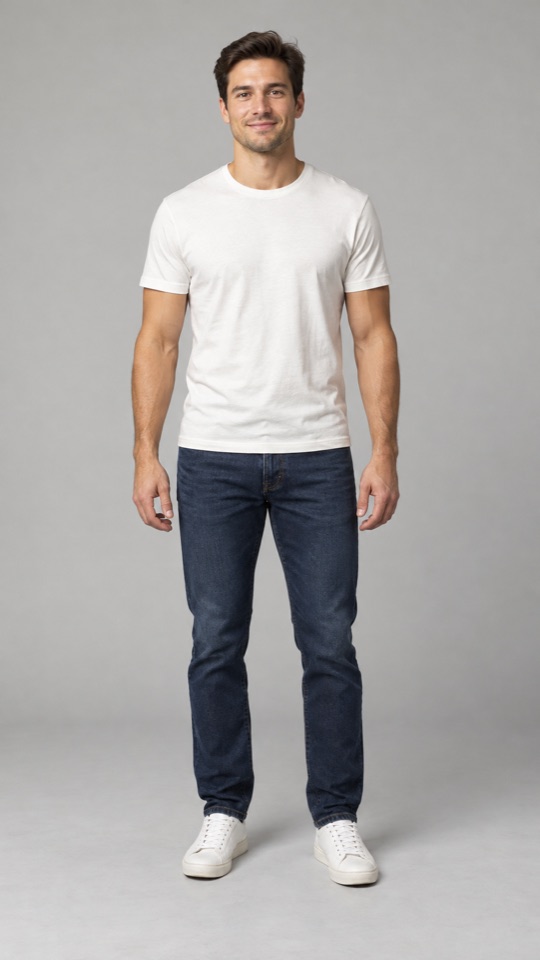
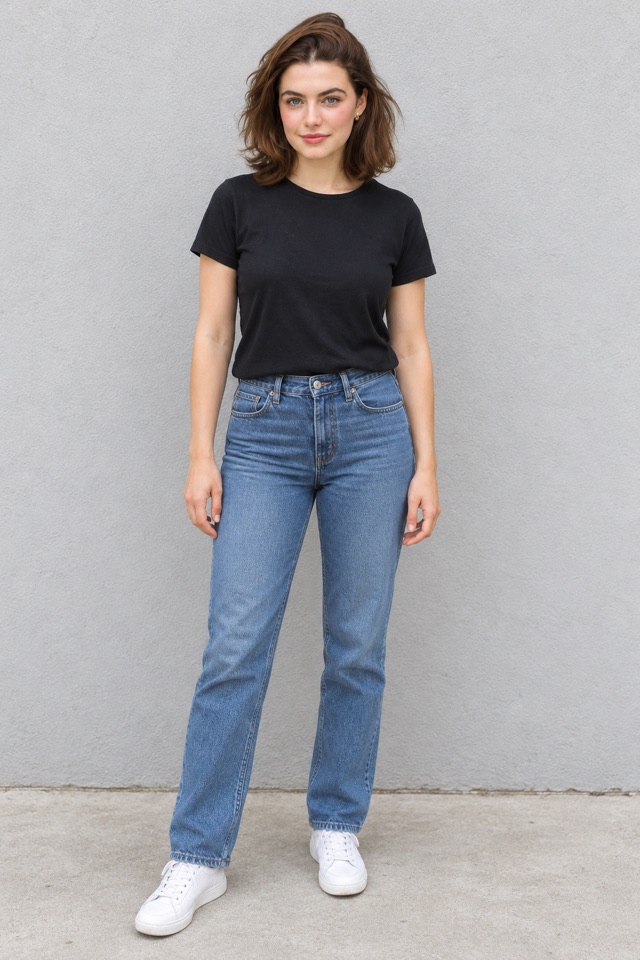
These are the actual inputs for this example. They are AI-generated adults, not customer photos.
After
15-second output
What can vary
Faces, hair, hands, clothing details and movement can vary by source photo and AI generation. Use a clear, well-lit, front-facing portrait with one visible adult per image. A stronger input helps, but it does not guarantee an exact likeness.
- Exactly three adult portraits
- 15-second vertical 9:16 video
- 720p MP4, fixed soundtrack and no watermark
- 100 credits per generation